forward deployed ai · 7im · london
Mohamad Kanso I build AI agents that hold up in the real world.
Senior Forward Deployed AI Associate at 7IM, designing, deploying and governing agents. In the open, I contribute to Hermes Agent by Nous Research.
- lower pipeline latency across 50m-record datasets · cognizant
- 40%
- global account of the year
cognizant · 2026 - Impact Award
00 · thesis
Messy in. Meaning out.
The interesting problems rarely arrive clean. They arrive as fragmented context, risky transcripts, failing pipelines, noisy markets and ambiguous decisions.
My work is the layer in between: structuring the noise, adding guardrails and shipping a system that holds up in the real world.
01 · selected systems
Built to survive contact with reality.
Ten systems, ranked for AI-agent work: open-source agent contributions first, then the agent, evaluation and safety systems I build myself. Nine have a live demo you can open in the browser.
-
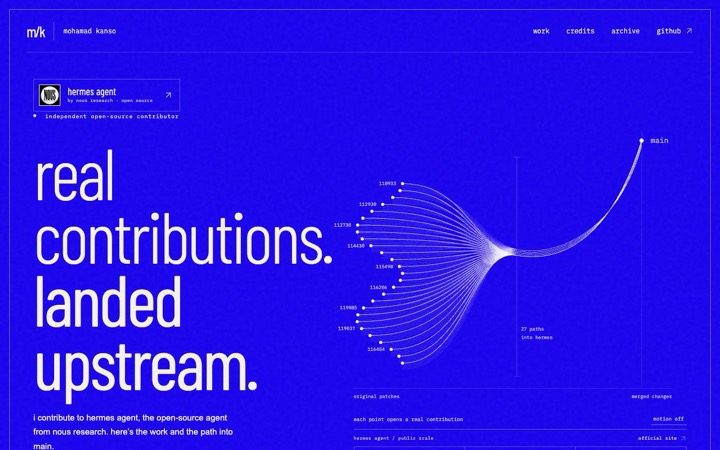
Hermes Agent
Open-source contributions to the agent from Nous Research.
- problem
- Agents lose context, sessions and routing at the boundaries: a compaction drops history, a session switches mid-turn, a provider alias routes two ways.
- what i built
- Fixes to session recovery, provider routing, scheduler reliability and tool safety, proposed as pull requests and carried into main by the maintainers.
- proof
- 27 contributions landed and 34 commits credited on main (21 authored, 13 co-authored), with maintainer credit linked for every one.
-
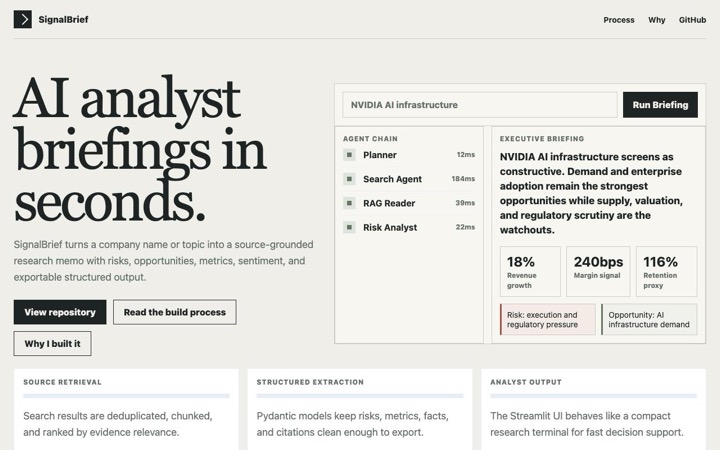
SignalBrief
Six specialist agents assemble an executive briefing without losing the evidence.
- problem
- Research scattered across sources, opinions and incompatible formats.
- what i built
- LangGraph agents, typed facts, evidence indexing, risk scoring, sentiment and visual analysis.
- proof
- Deterministic fallback means the demo still tells the truth.
-
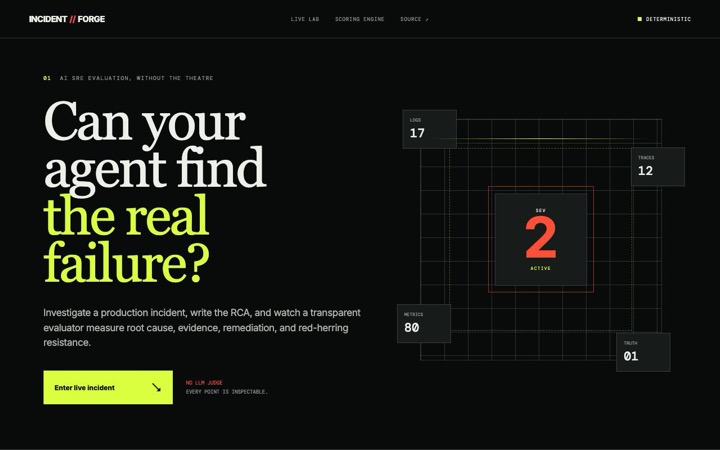
IncidentForge
A proving ground for AI agents that claim they can diagnose production incidents.
- problem
- Alerts, metrics, logs, traces and runbooks all telling fragments of the same failure.
- what i built
- Synthetic incident bundles, ground truth and RCA scoring for repeatable AI SRE evaluation.
- proof
- Open benchmarks over vague agent claims.
-
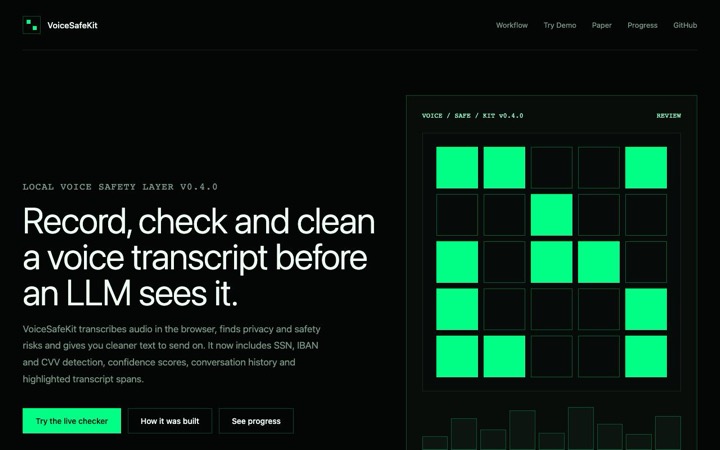
VoiceSafeKit
A safety gate for voice assistants, before sensitive words reach an LLM.
- problem
- Raw voice transcripts can quietly contain credentials, identity data and private context.
- what i built
- Classifies every transcript as SAFE, REDACT, REVIEW or BLOCK, with browser recording and CLI support.
- proof
- Local-first, open source and built around visible decisions.
-
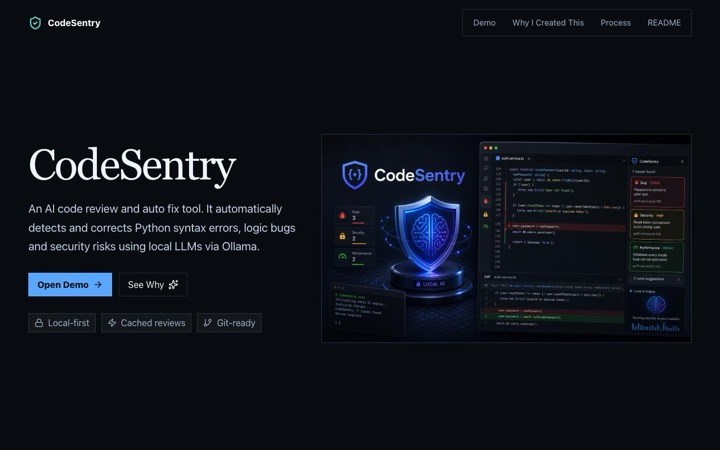
CodeSentry
Local AI code review that finds the risk and proposes the fix.
- problem
- Syntax failures, logic bugs and security risks buried across a codebase.
- what i built
- Local LLM review, auto-fix routes, cached scans, Markdown reports and CI checks.
- proof
- Private by design, with a working browser experience.
-
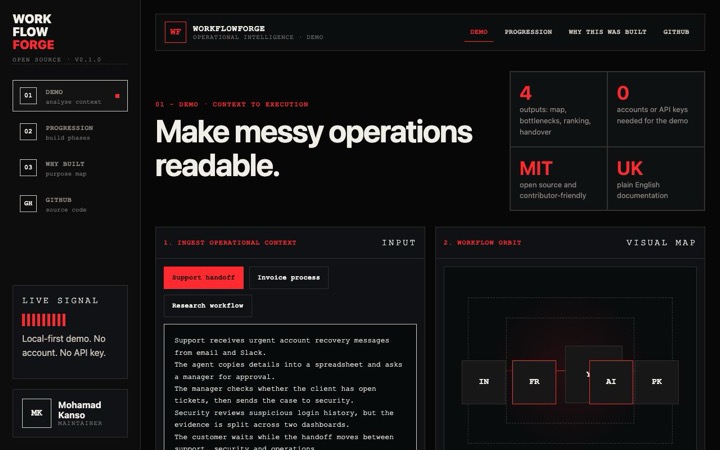
WorkflowForge
Turns operational chaos into a map teams can actually execute.
- problem
- Scattered documents, tribal knowledge and invisible bottlenecks.
- what i built
- Python workflow mapping, bottleneck analysis, Mermaid diagrams and ranked automation opportunities.
- proof
- Open source with a live, explorable demo.
-
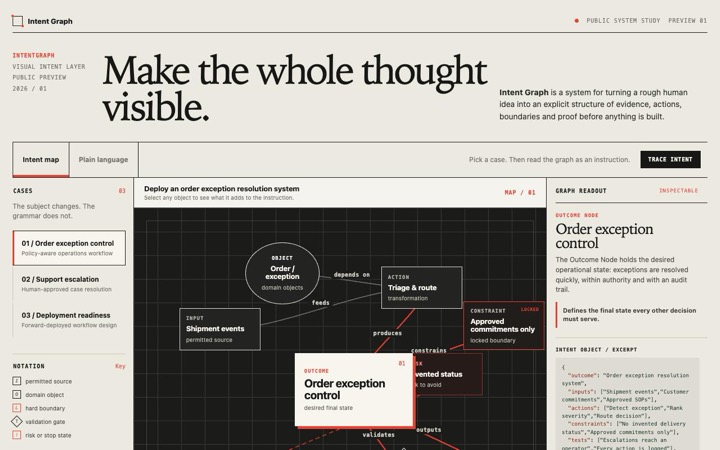
Intent Graph
Preserving intent before language flattens it.
- problem
- Humans think in mental models, but turning those models into prose or prompts quietly loses relationships, constraints and success conditions.
- what i built
- An outcome-centred visual workspace compiles connected inputs, actions, rules, risks and tests into a machine-readable Intent Object.
- proof
- A local compiler, Intent Mentor, validation gates, version history and graph diffs turn messy ideas into Codex-ready execution contracts.
portfolio preview · limited demonstration only, not the full private system
-
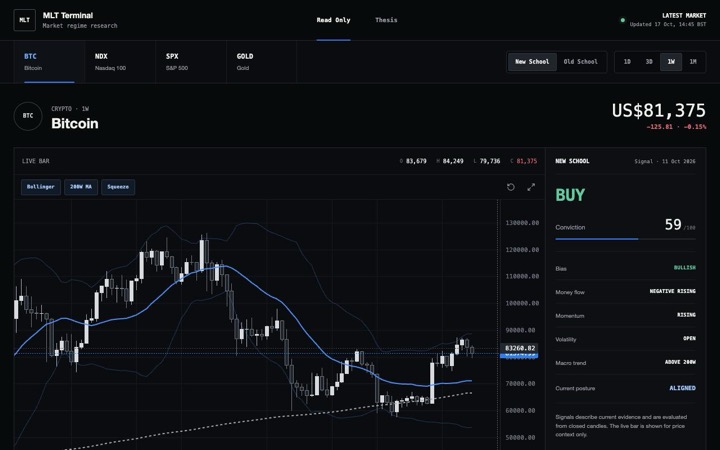
MLT Terminal
Directional quality, not prediction theatre.
- problem
- Technical indicators produce conflicting signals and false certainty about where markets go next.
- what i built
- Scores money flow, momentum curvature, squeeze conditions, trend context and structure across multiple timeframes.
- proof
- Fixed-horizon replay and reliability matrices test every regime call against historical outcomes.
portfolio preview · limited demonstration only, not the full private platform
-
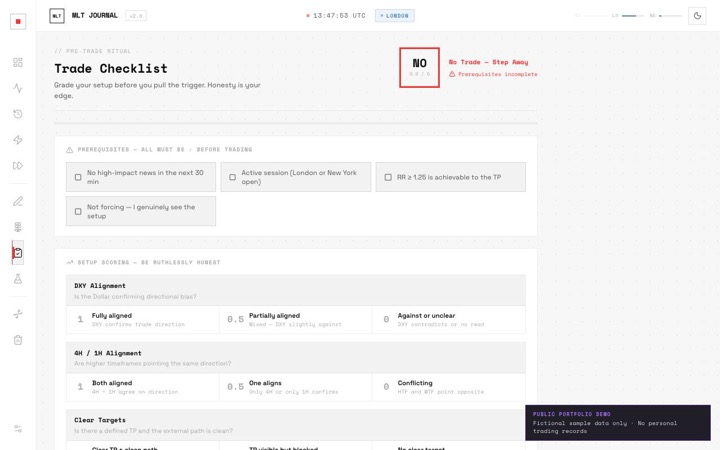
MLT Journal
A trading-journal analytics tool that turns each trade into structured, reviewable evidence.
- problem
- Trader memory is selective: results get separated from setup quality, psychology, rule compliance and market context.
- what i built
- A fully local Flask + React journal with 39+ trade fields, screenshots, live, backtest and forward-test workflows.
- proof
- Journal analytics, setup and session breakdowns, psychology review, SQLite privacy and an optional MT5 bridge.
-
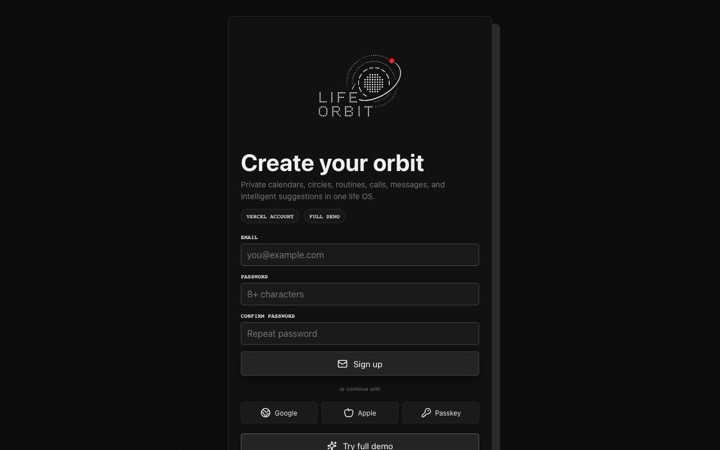
Life Orbit
A calmer social layer for real life.
- problem
- Goals, routines, relationships and time live in disconnected tools while social products optimise for performance.
- what i built
- People, goals, tasks and events orbit a person as living context, with flexible privacy and availability sharing.
- intent
- Use intelligence to help people coordinate better without turning life into another public feed.
private repository · safe demo mode
02 · more builds
The lab stays switched on.
Local agents, voice interfaces, research systems and tools built to answer questions I could not leave alone.
-
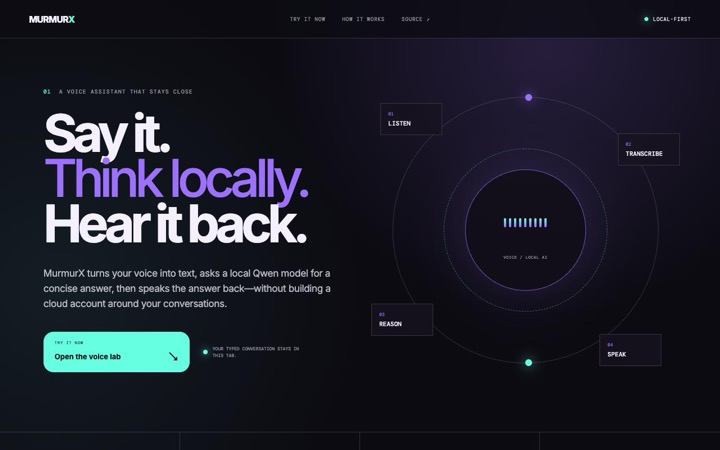 MurmurX
Speak to a real browser-local Qwen model. Try the voice lab ↗
- Bitcoin ML System LSTM, indicators and walk-forward testing. ↗
-
Enterprise AI Assistant RBAC, approved tools, PostgreSQL retrieval and human review.
03 · how i think
Four layers. One useful output.
Great AI is rarely one model. It is a chain of choices about context, structure, constraints and evidence.
- 01
Context
I begin with the actual inputs, users, risks and constraints, not a model looking for a problem.
proven in workflowforge · incidentforge - 02
Structure
I turn ambiguous material into typed facts, explicit routes and components that can be inspected.
proven in signalbrief · enterprise ai assistant - 03
Guardrails
I design the unsafe, uncertain and human-review paths before the happy path gets impressive.
proven in voicesafekit · codesentry - 04
Evidence
I use evaluation, traces, observability and measurable outcomes to prove the system works outside the demo.
proven in incidentforge · cognizant delivery
04 · proof, not claims
The work leaves receipts.
Commercial delivery, public systems, academic depth and recognition for turning up when the problem gets difficult.
-
aug 2026 — now
7IM
Senior Forward Deployed AI Associate
- Design and deploy AI agents across private wealth, sales and M&A.
- Co-lead the firm's AI agent governance framework: lifecycle, release gates, inventory and controls.
-
sep 2026 — now · open source
Hermes Agent
Contributor · Nous Research
- 27 contributions landed in the Nous Research agent, with 21 authored and 13 co-authored commits on main.
- see the record ↗
-
may 2025 — aug 2026
Cognizant
Graduate, Artificial Intelligence & Analytics
employment verification available on request
- Built RAG enterprise search and Q&A prototypes with metadata-aware retrieval, grounding and access controls.
- Designed structured-data assistants with approved tool calls, RBAC, traceability and human review.
- Improved ADF-to-Databricks pipelines for a UK public-sector finance client, cutting latency 40% across 50M-record datasets.
-
sep 2024 — apr 2025
Independent ML + AI engineering
- Built local voice AI, financial time-series systems and applied ML experiments with privacy and evaluation in the loop.
- Team Award — Owning It 2025
- Computer Vision Challenge Winner 2023
- Senior Maths Challenge Silver 2020
05 · the human
I care about the moment an ambitious idea becomes real, legible and useful.
I am a Senior Forward Deployed AI Associate at 7IM in London, designing and deploying AI agents and co-leading how the firm governs them. Before that I built RAG, agent and data-engineering systems at Cognizant, and in the open I contribute to Hermes Agent, where 27 of my contributions have landed upstream. I like problems with messy edges: the ones where evaluation, guardrails and product judgement matter as much as the model.
- now
- 7IM · Forward Deployed AI
- education
- MSci Data Science · City, University of London
- focus
- AI agents · evaluation · governance · RAG
- based
- London, United Kingdom
06 · open-source atlas
Every public experiment.
- WorkflowForgepython · workflow intelligence
- VoiceSafeKitpython · voice privacy
- CodeSentrypython · local code intelligence
- SignalBriefpython · agent research
loading the complete public archive
open github profile ↗07 · contact